Composite Buffers
In real protocols often a message to be transmitted is composed of a couple of chunks prepared separately in separate contiguous regions of storage. For instance, you may separately get message headers, the payload, and the message checksum. Trying to get them into a single contiguous storage would require the user to do unnecessary copying.
In order to address this use case, all read and write operations in Capy allow you to provide ranges of contiguous buffers:
const std::string headers = make_headers();
const std::string body = make_body();
const std::string checksum = stamp(headers, body);

std::array buf {capy::make_buffer(headers),
                capy::make_buffer(body),
                capy::make_buffer(checksum)};

co_await stream.write_some(buf);
Buffer Sequences
In order to address both the simple case of a single contiguous buffer, and the complex cases when the data is produced in a number of contiguous buffers, Capy introduces a concept of a buffer sequence:
-
A contiguous buffer is a buffer sequence.
-
Any bidirectional range over contiguous buffers is a buffer sequence.
This generalizes the notion of a handle:
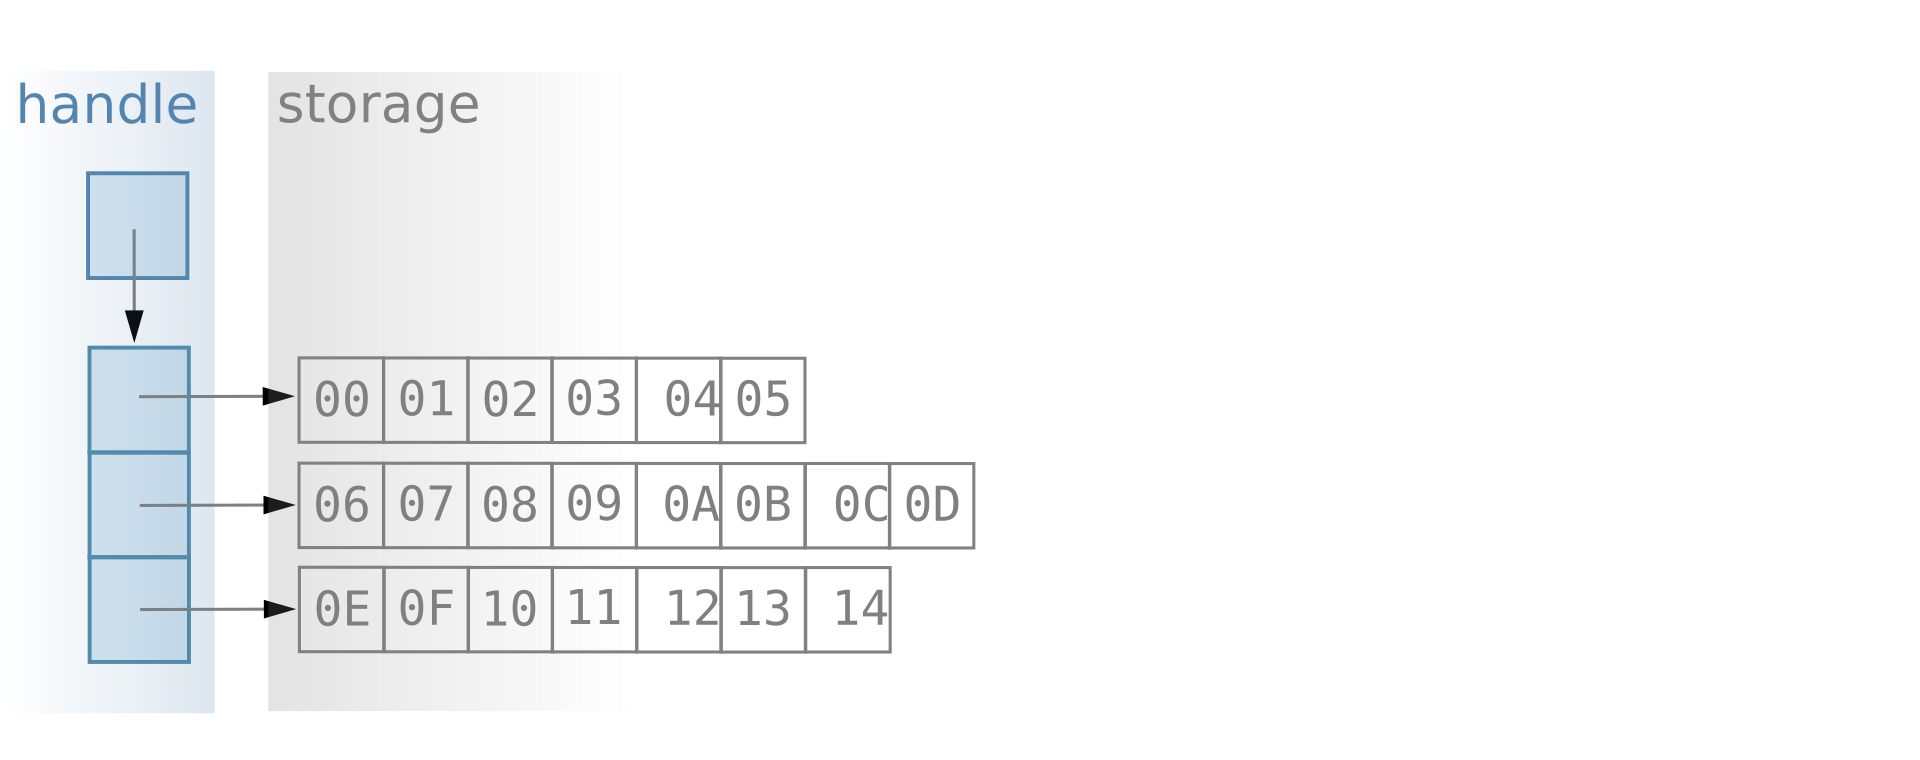
In the composite case, the entire range mechanism becomes a handle; but since the elements are
const_buffer or mutable_buffer,
the contiguous regions of memory they point to are not part of the handle.
This still allows the algorithms to copy the handle
while retaining the storage at its original location.
Treating a single contiguous buffer as a one-element sequence is intentional, to make the library API smaller. Internally, it is treated as a single-element range.
While a structure looks two-dimensional, the bytes across all contiguous buffers are interpretted and transmitted as a single sequence: first the bytes from the first contiguous buffer, then the bytes from the second contiguous buffer, and so on.
The mechanism for handling ranges of buffers assumes that the number of elements will be around four. In fact, some implementations will perform suboptimally when you use ranges of more than 16 contiguous buffers.
Serializing more buffers in one transmission would not be efficient, and you might as well merge the contents into a single buffer.
The Concepts
Concept MutableBufferSequence tests if the type models a mutable buffer sequence,
suitable for read algorithms. It can be one of:
-
a bidirectional range of
mutable_buffer.
static_assert(capy::MutableBufferSequence<capy::mutable_buffer>);
static_assert(capy::MutableBufferSequence<std::span<capy::mutable_buffer>>);
static_assert(capy::MutableBufferSequence<std::vector<capy::mutable_buffer>>);
static_assert(capy::MutableBufferSequence<std::array<capy::mutable_buffer, 4>>);
Concept ConstBufferSequence tests if the type models a const buffer sequence,
suitable for write algorithms. It can be one of:
-
mutable_buffer(with caveat that its data has determinate values), -
a bidirectional range of either
const_bufferormutable_buffer.
static_assert(capy::ConstBufferSequence<capy::const_buffer>);
static_assert(capy::ConstBufferSequence<capy::mutable_buffer>);
static_assert(capy::ConstBufferSequence<std::span<capy::const_buffer>>);
static_assert(capy::ConstBufferSequence<std::span<capy::mutable_buffer>>);
static_assert(capy::ConstBufferSequence<std::array<capy::const_buffer, 4>>);
static_assert(capy::ConstBufferSequence<std::array<capy::mutable_buffer, 4>>);
These concepts are present in header <boost/capy/buffers.hpp>.
Iterating Buffer Sequences
Use begin() and end() from <boost/capy/buffers.hpp>:
template<capy::ConstBufferSequence Buffers>
void process(Buffers const& bufs)
{
    for (auto it = capy::begin(bufs); it != capy::end(bufs); ++it)
    {
        capy::const_buffer buf = *it;
        // Process buf.data(), buf.size()
    }
}
These handle both single buffers, returning pointer-to-self, and ranges, returning standard iterators:
capy::const_buffer single;
auto it = capy::begin(single);  // Returns pointer to single
auto e = capy::end(single);     // Returns pointer past single

std::array<capy::const_buffer, 3> multi;
auto it2 = capy::begin(multi);  // Returns multi.begin()
auto e2 = capy::end(multi);     // Returns multi.end()
buffer_slice
buffer_slice returns a byte sub-range of a buffer sequence, as a value:
#include <boost/capy/buffers/buffer_slice.hpp>

// send only the first 16 KB
co_await capy::write(stream, capy::buffer_slice(bufs, 0, 16384));
// everything after the first 16 KB
auto rest = capy::buffer_slice(bufs, 16384);
co_await capy::write(stream, rest);buffer_slice(seq, offset, length) returns a value that is itself a buffer sequence, so you can pass it to any operation expecting one. Both offset and length are optional, which makes it a general byte sub-range primitive. Except in the single-buffer case the result borrows seq, so the sequence must outlive the slice.
Capy creates and manages buffer handles on your behalf. Those are the sub-range a buffer_slice produces, and the descriptors a type-erased stream passes to the OS. Each is valid only for the window its API documents.
consuming_buffers
When transferring data incrementally, consuming_buffers is a cursor that tracks progress:
#include <boost/capy/buffers/consuming_buffers.hpp>

template<capy::MutableBufferSequence Buffers>
capy::task<std::size_t> read_all(Stream& stream, Buffers buffers)
{
    capy::consuming_buffers consuming(buffers);
    std::size_t const total_size = capy::buffer_size(buffers);
    std::size_t total = 0;

    while (total < total_size)
    {
        auto [ec, n] = co_await stream.read_some(consuming.data());
        consuming.consume(n);
        total += n;
        if (ec)
            break;
    }

    co_return total;
}
The cursor borrows the underlying sequence and provides:
|
A coroutine reads its parameters when its body runs, not when the call is written. A task that is stored and awaited later outlives its call expression, so a reference parameter can dangle by then. That is why the fan-out example on Concurrent Composition takes its item by value: it collects its tasks first, then awaits them together. |
Rationale
Why void* rather than std::byte?
Two concrete forces decide it:
-
The platform types already use it. The OS structures Capy maps onto are
void*orchar*:iovec’s `iov_base,WSABUF’s `buf. The pointer field never needs reinterpreting. -
Callers supply many element types. Data arrives as
char[],unsigned char[],std::byte[],std::string, and more. One neutral pointer erases all of them to a single representation.std::span<std::byte>would make every caller reinterpret first, andstd::span<void>is ill-formed.
This is an argument from layout and from caller convenience, not from semantics. "Raw memory" describes std::byte just as well as it describes void*.
Why concepts rather than one span type?
std::span<std::span<std::byte>> is the reflexive answer for multiple buffers, and it works. The problem is composition. Joining a two-buffer header to a three-buffer body means building a new five-element array, so every composition allocates:
HeaderBuffers headers{ /* ... */ };
BodyBuffers body{ /* ... */ };

// To combine, you MUST allocate a new array:
std::array<std::span<std::byte const>, 5> combined;
std::copy(headers.begin(), headers.end(), combined.begin());
std::copy(body.begin(), body.end(), combined.begin() + 2);

write_data(combined);
A concept accepts the composite directly, with no allocation and no overload per shape.
At type-erasure boundaries the tradeoff reverses. Virtual functions need concrete types, so Capy converts to concrete descriptors internally and keeps concepts at the user-facing edge.
Why Bidirectional?
The concepts require bidirectional ranges, not merely forward ranges, for two reasons:
-
Some algorithms traverse buffers backwards
-
The slice views from
buffer_sliceandconsuming_buffers::data()must adjust the first and last buffers' bounds
If your custom sequence offers only forward iteration, wrap it in a type that provides bidirectional access.